Bhaven
Naik
LLM Infrastructure · RAG Systems · MLOps · AI Platform Engineering
Building production-grade LLM systems, RAG pipelines, and ML infrastructure. 3+ years delivering enterprise GenAI — from data ingestion to scalable inference in regulated and air-gapped environments.
Core stack
About
Building AI that ships to production
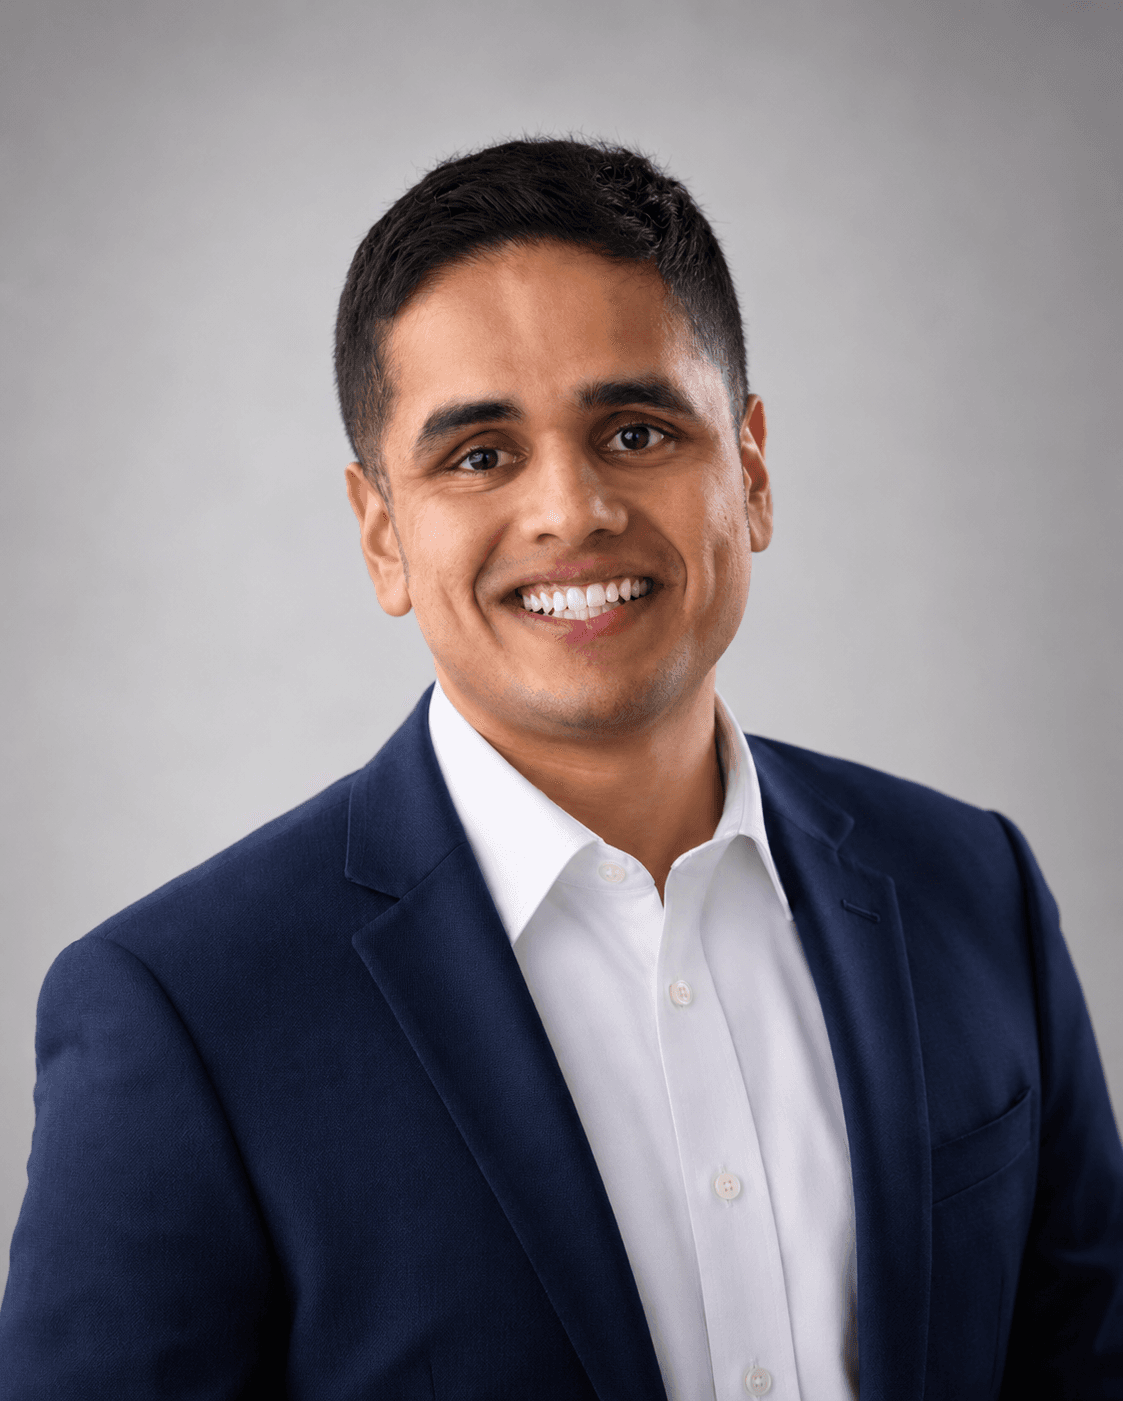
Bhaven Naik
ML Engineer
Toronto, ON
ML Engineer at CreatorIQ with 3+ years of production experience building and deploying end-to-end LLM applications, RAG systems, and scalable ML infrastructure. Deep expertise in Generative AI, LLM orchestration, retrieval-augmented generation, and MLOps. I bridge research and real-world impact — from data ingestion and model development to scalable inference, monitoring, and operationalization in enterprise and air-gapped environments.
I'm particularly passionate about designing robust AI platforms, retrieval-augmented generation systems, and cloud-native ML infrastructure. My focus is on bridging research and real-world impact — building reliable, scalable, maintainable solutions that work in regulated and constrained environments.
Based in downtown Toronto.
3+
Years production AI
2
Enterprise RAG systems
Education
Master of Applied Computer Science
St. Francis Xavier University · 2020 – 2022
Bachelor of Computer Engineering
University of Mumbai · 2016 – 2020
Certifications
IBM Machine Learning Essentials
IBM · 2022
Experience
Where I've built things
Projects
Things I've built
Production systems, research projects, and open-source work. NDA-protected systems are described architecturally — the patterns are mine to share.
Air-Gapped RAG Platform
Production Q&A system for regulated enterprise environments
Architected and deployed a production-grade, deterministic RAG system fully deployable in secure air-gapped enterprise environments — zero external API calls. Docling-powered document ingestion, semantic chunking, vector embedding via Sentence Transformers, and vLLM-served LLM inference behind FastAPI microservices.
GraphRAG Due Diligence Tool
Knowledge-graph-powered due diligence document analysis
Knowledge-graph-powered analysis platform for due diligence workflows. Automated multi-source ETL and multi-document summarization via LLM pipelines. Meaningfully reduced manual research and analyst time.
DCGAN Video Augmentation
GAN-based data augmentation for human action recognition
Research implementation of a Deep Convolutional GAN for Human Action Recognition data augmentation on the HMDB51 dataset. Scalable training pipeline with multi-GPU support, benchmarked against pre-trained PyTorchVideo classifiers.
Diabetic Retinopathy Classifier
End-to-end medical AI with web deployment on AWS
Fine-tuned VGG16 to classify 5 severity grades of diabetic retinopathy from fundus images. Built a Flask web interface and deployed on AWS EC2 for clinical accessibility.
Skills
What I work with
Generative AI & LLMs
RAG & Search
MLOps & Infrastructure
Cloud & DevOps
ML & Deep Learning
Data & Streaming
Contact
Let's build something
Working on something interesting in LLMs, RAG, or ML infrastructure? Always happy to connect with people building in this space — whether it's a technical question, a collaboration, or just a conversation.
Get in touch